
uvunwrap
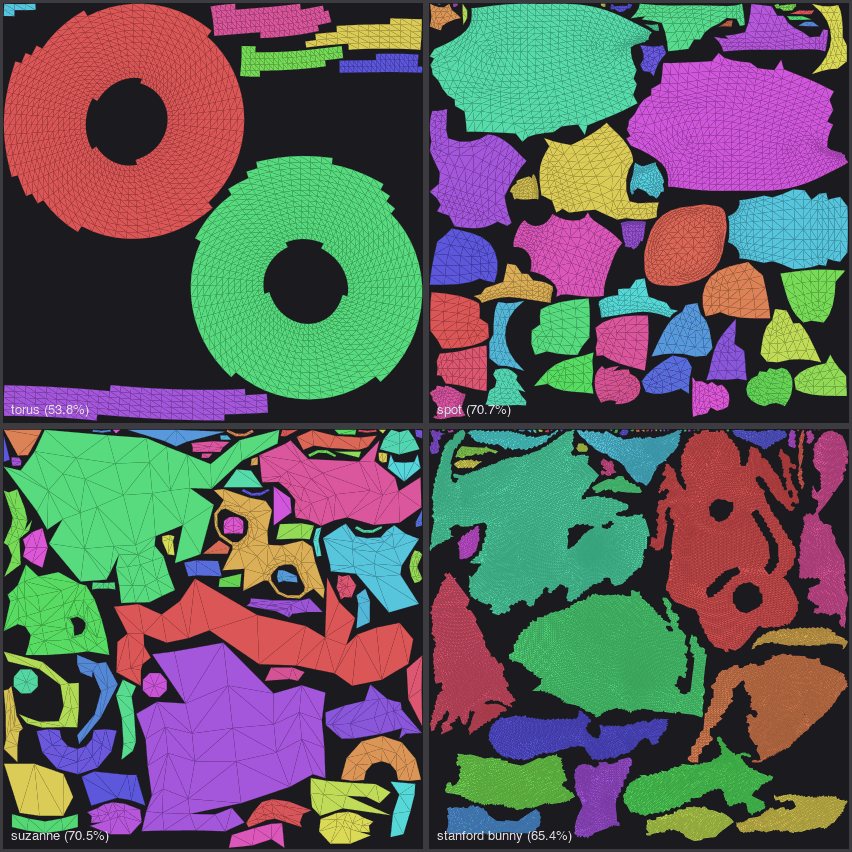
Pure-Rust automatic UV unwrapping: generates unique, non-overlapping texture coordinates for lightmaps, texture baking and texture painting. Inspired by xatlas, with no C++ toolchain required, so it builds for wasm and cross-compiles trivially.
Usage
use ;
let mesh = new;
let atlas = generate?;
for v in &atlas.meshes.vertices
// Engines usually want a fixed texel density (5 texels per unit here), on a
// page that grows to fit or on as many fixed-size pages as needed:
let options = Options ;
Density::Auto { page_size } (the default, 1024) picks the highest density
that fits one page. generate_with_progress takes a callback that receives
the current stage and progress counts and can return false to cancel, for
running large unwraps as background tasks.
Output meshes keep the input triangles in order; vertices on chart seams are
duplicated, and xref maps each one back to its input vertex.
Pass meshes as your engine stores them, with vertices split for normals and UVs: identical positions are welded, and the split edges (hard edges, UV seams) become chart boundaries. Optional per-mesh inputs:
face_materials: charts never span two materials.ignored_faces: faces that get no UV space.polygons: for meshes triangulated from quads and n-gons, the polygon each triangle came from. A polygon's triangles always share a chart, so every polygon corner gets exactly one UV, as UV maps that store one UV per corner (e.g. Blender's) require.scale: mesh-to-world scale, so differently scaled instances share one texel density.instance_scales: one scale per instance of a mesh drawn several times. The mesh is unwrapped once (its UVs cover[0, 1]) and each instance gets its own rectangle in the atlas (OutputMesh::instances), the way engines lightmap shared meshes (e.g. Bevy'sLightmap::uv_rect). With one instance this also keeps a mesh on a single page.existing_uvs: existing UVs to repack instead of unwrapping: each UV island becomes one chart, rescaled to its surface area for uniform texel density. Mirrored islands are flipped; unusable ones are unwrapped normally.
Try it on an OBJ file (writes an OBJ with vt coordinates plus an SVG per page):
How it works
- Topology: welds identical positions, drops triangles too thin for f32 UVs (and ignored ones), and connects faces only across manifold, consistently oriented edges within one material that the input doesn't split. Split edges are ignored when most edges are split (flat shading).
- Segmentation: grows charts from the largest planar regions, xatlas
style: candidates are ranked by normal deviation (on crease-preserving
smoothed normals, limited by
max_chart_angle), with bonuses for filling boundary notches and penalties for crossing creases. Small charts mostly enclosed by a neighbor are merged, and single-triangle teeth are smoothed off the boundaries. - Parameterization: planar projection for flat charts, otherwise Least
Squares Conformal Maps solved by sparse Cholesky. Results with flipped
triangles, overlaps or area distortion above
max_area_distortionare split and retried, so output is always valid. Large, strongly curved charts are split without attempting a solve. - Packing: charts are rotated to their minimum-area bounding rectangle,
rasterized (conservatively, dilated by the padding) and packed by shape, so
they nest into each other's concavities and holes, with 90° rotations.
Texel density is automatic (fit one page) or fixed (one growing page, or
multiple fixed-size pages).
Packing::Fastinstead folds charts into rows and pushes each row up against the previous ones by the charts' outlines (after TABI, Gu, Vining & Sheffer 2026): milliseconds for thousands of charts, but it can't use holes or the space under overhangs, so atlases are less dense.max_chart_sizescales oversized charts down;block_aligngives every chart its own 4×4 texel blocks for block-compressed lightmaps.
Features
| Feature | Default | Effect |
|---|---|---|
direct-solver |
yes | Sparse Cholesky via pure-Rust faer; about 10× faster on large charts. Without it, an iterative CGLS solver is used. |
parallel |
yes | Parameterizes charts in parallel with rayon. Disable for wasm32 without threads. |
With no default features the crate has zero dependencies.
Determinism
The same input, options and features give bit-identical output on any thread
count. No platform math library calls are used, so without direct-solver
output depends only on IEEE-754 arithmetic and matches across platforms: CI
compares output hashes on Linux x86-64 and ARM64, macOS ARM64, Windows
x86-64, wasm32-wasip1 (wasmtime) and wasm32-unknown-unknown (Node). With
direct-solver, faer selects SIMD kernels at runtime, so output can differ
between CPU architectures. If you cache unwraps or bake on one machine and
ship to another, build without it. The unwrap example prints an output hash
for comparing builds.
Performance
1024×1024 page, 2 texels of padding, release build, Apple M5 (10 cores). Utilization is true surface area over atlas area.
| Model | Triangles | Charts | Single core | Multi-core | Utilization |
|---|---|---|---|---|---|
| Spot | 5.9K | 47 | 27 ms | 19 ms | 71% |
| Stanford bunny | 69K | 58 | 0.19 s | 82 ms | 65% |
| Armadillo | 100K | 257 | 0.40 s | 0.16 s | 60% |
| Nefertiti | 100K | 456 | 0.74 s | 0.40 s | 64% |
| Igea | 269K | 83 | 0.96 s | 0.48 s | 66% |
cargo bench runs criterion benchmarks on procedural meshes, plus any of
spot, beetle, bunny, armadillo, nefertiti and igea found in
models/; scripts/fetch-models.sh downloads them from
common-3d-test-models
at a pinned commit.
License
MIT