
mongol-norm


English
[!WARNING] Beta.
shape/same_shapeshould be stable. Thenormalizeoutput currently encodes by glyph shape, not the standard phonetic (nominal-character) spelling, and may change in a later release. For example ᠮᠣᠩᠭᠣᠯ (MA+O+ANG+GA+O+LA) normalizes to ᠮᠣᠠᠭ᠌ᠨ᠋ᠨ᠋ᠣᠯ (MA+O+A+GA+FVS2+NA+FVS1+NA+FVS1+O+LA). If you store normalized keys, storecanonical_version()with them and rebuild when it changes.
mongol-norm tells whether two Traditional Mongolian (Hudum) strings look the same, and maps them to one key. Rust crate with zero dependencies, plus a Python package and a CLI.
Why
The same visible Mongolian word can be typed as many different Unicode sequences — A/E look alike in medial and final position, O/U and OE/UE share forms, FVS selectors and joiners (nirugu, ZWJ) can produce the same glyph in several ways. So search misses matches, deduplication fails and index keys differ for words that look identical.
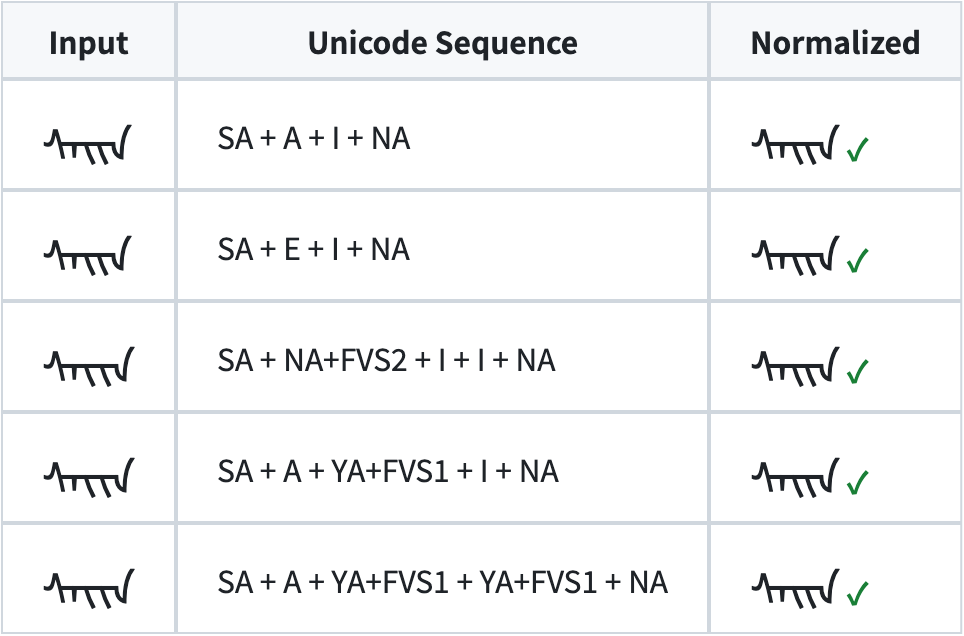
mongol-norm runs the UTN #57 v4 shaping rules (no font needed) to get the written units a font would draw:
shape(word)— the written-unit sequence, a fingerprint of the visible wordsame_shape(a, b)— do two encodings render identically?normalize(word)/normalize_text(text)— one canonical Unicode string per shape
Use it for search and indexing, deduplication, corpus counts, spell-check lookup, and cleaning OCR or input-method output.
Install
Rust (MSRV 1.82, zero dependencies, also builds for wasm32-unknown-unknown):
or in Cargo.toml:
[]
= "0.2.3"
Python (CPython ≥ 3.9, no runtime dependencies, no Rust toolchain needed):
Prebuilt wheels cover Linux x86_64 / aarch64 (glibc and musl), macOS x86_64 / Apple silicon and Windows x64. On other platforms pip builds from the source distribution, which needs Rust ≥ 1.83.
Command line — either of these puts mongol-norm on PATH:
Rust
use ;
Full API on docs.rs.
Python
=
# → ['S', 'A', 'I', 'I', 'A']
# → True
# → 'ᠰᠠᠢ᠍ᠢ᠍ᠠ᠌'
# → 'Hello ᠰᠠᠢ᠍ᠢ᠍ᠠ᠌ world'
# Deduplicate
# → {'ᠰᠠᠢ᠍ᠢ᠍ᠠ᠌'}
More in the Python README.
Command line
mongol-norm --help lists every option.
Notes
- Normalization covers MNG (Hudum) only. Todo, Sibe and Manchu (
TOD/SIB/MCH) shape but do not normalize yet. - A word whose shape the built-in table cannot encode fails with an error rather than being
guessed;
normalize_allow_fallback(Python:strict=False) returns it unchanged instead. - Shaping passes 100% of mongfontbuilder's
core-hudand GB/T 25914-2023eac-hudsuites; normalization round-trips every corpus word (shape(normalize(x)) == shape(x)). - This project was written with Claude Code; tests and core code were reviewed by hand. Please report problems as issues.
More
docs/internals.md— shaping pipeline, duplicate encodings, normalization algorithmdocs/data-format.md— JSON rule tables, for ports to other languagesdocs/development.md— repository layout, running the testsdocs/releasing.md— cutting a release
License
MIT — see LICENSE. Shaping rules and data are derived from UTN #57 and mongfontbuilder (MIT) by Kushim Jiang; test suites from mongfontbuilder and GB/T 25914-2023. Notices in NOTICE.
中文
[!WARNING] Beta 版。
shape/same_shape应该是稳定的。normalize的输出目前是按字形编码的,不是按读音 书写的标准名义字符序列,后续版本有可能修改。例如 ᠮᠣᠩᠭᠣᠯ(MA+O+ANG+GA+O+LA)规范化后是 ᠮᠣᠠᠭ᠌ᠨ᠋ᠨ᠋ᠣᠯ (MA+O+A+GA+FVS2+NA+FVS1+NA+FVS1+O+LA)。如果要持久化规范化后的 key,请同时保存canonical_version(),版本变化时重建。
mongol-norm 判断两段传统蒙古文(回鹘式,Hudum)是否外形相同,并把它们映射成同一个 key。零依赖 Rust crate,另有 Python 包和命令行工具。
为什么
同一个看起来一样的蒙古文词,可以用很多种 Unicode 序列输入——A/E 在词中、词尾同形,O/U、OE/UE 共享字形, FVS 和连接符(nirugu、ZWJ)也能用不同方式得到同一个字形。结果是:搜索找不到、去重失败、同一个词索引 key 不同。
mongol-norm 按 UTN #57 v4 的整形规则(不需要字体) 算出字体会画出的书写单元:
shape(word)—— 书写单元序列,即可见词形的指纹same_shape(a, b)—— 两种编码渲染结果是否相同normalize(word)/normalize_text(text)—— 同一个 shape 只输出一个 Unicode 字符串
用途:搜索和索引、去重、语料词频统计、拼写检查前的查词、清洗 OCR 或输入法输出。
安装
Rust(MSRV 1.82,零依赖,可编译到 wasm32-unknown-unknown):
或写进 Cargo.toml:
[]
= "0.2.3"
Python(CPython ≥ 3.9,无运行时依赖,不需要 Rust 工具链):
预编译 wheel 覆盖 Linux x86_64 / aarch64(glibc 与 musl)、macOS x86_64 / Apple silicon、Windows x64。 其他平台 pip 会从源码包构建,需要 Rust ≥ 1.83。
命令行——下面任意一种都会装上 mongol-norm 命令:
用法
Rust:
use ;
Python:
=
# → ['S', 'A', 'I', 'I', 'A']
# → True
# → 'ᠰᠠᠢ᠍ᠢ᠍ᠠ᠌'
# → 'Hello ᠰᠠᠢ᠍ᠢ᠍ᠠ᠌ world'
# 去重
# → {'ᠰᠠᠢ᠍ᠢ᠍ᠠ᠌'}
命令行:
完整 API 见 docs.rs 和
Python 文档;mongol-norm --help
列出全部参数。
说明
- 规范化目前只支持 MNG(回鹘式)。托忒文、锡伯文、满文(
TOD/SIB/MCH)只能整形。 - 内置表无法编码的 shape 会报错而不是乱猜;
normalize_allow_fallback(Python:strict=False)则原样返回。 - 整形 100% 通过 mongfontbuilder 的
core-hud与 GB/T 25914-2023eac-hud测试集;规范化对全部语料词 满足shape(normalize(x)) == shape(x)。 - 本项目用 Claude Code 编写,测试与核心代码经人工审核。遇到问题请提 issue。
许可
MIT,见 LICENSE。整形规则与数据源自 UTN #57 和 Kushim Jiang 的 mongfontbuilder(MIT);测试集来自 mongfontbuilder 与 GB/T 25914-2023。声明见 NOTICE。