
Kjarni
Run transformer models inside your program, in any language. Same output as PyTorch.
Kjarni is a transformer inference library written in Rust: embeddings, classification, reranking, search, chat, speech to text, summarization and translation, on CPU or GPU inside your process. This crate is its Rust API; the same engine ships for Python, C#, Go, C++ and the browser.
[]
= "0.2"
= { = "1", = ["macros", "rt-multi-thread"] }
use Embedder;
let embedder = new.await?;
println!; // 0.8598
println!; // 0.3379
Models load from HuggingFace safetensors and GGUF directly. The first call downloads
and caches under ~/.cache/kjarni; nothing leaves the machine.
What it implements
BERT-style encoders, cross-encoders, Llama-family decoders (Llama, Qwen2, Mistral, Phi-3), T5, BART and Whisper. Quantised weights in Q4_K, Q6_K, Q8_0 and Q8_K, on CPU with AVX2/FMA and NEON kernels or on GPU through WebGPU, which means no CUDA toolkit.
For an arbitrary research model, convert it and use ONNX Runtime. For embeddings, classification, reranking or chat inside a program that has to ship somewhere, this is one dependency with no toolchain.
The workspace
| Crate | What it is |
|---|---|
kjarni |
The public API. Start here. |
kjarni-transformers |
The engine: kernels, model graphs, CPU and GPU backends |
kjarni-models |
Model definitions and the registry |
kjarni-search |
Vector search primitives |
kjarni-rag |
Retrieval-augmented generation |
kjarni-cli |
The kjarni command line tool |
kjarni-ffi |
The C ABI every other language binding is built on |
How fast it is
An i7-13700 and an RTX A2000 12 GB, each engine in its own process. On this NVIDIA card, engines using CUDA are well ahead of Kjarni's WebGPU; what WebGPU gives you is the same code on NVIDIA, AMD, Intel and Apple hardware with nothing to install.
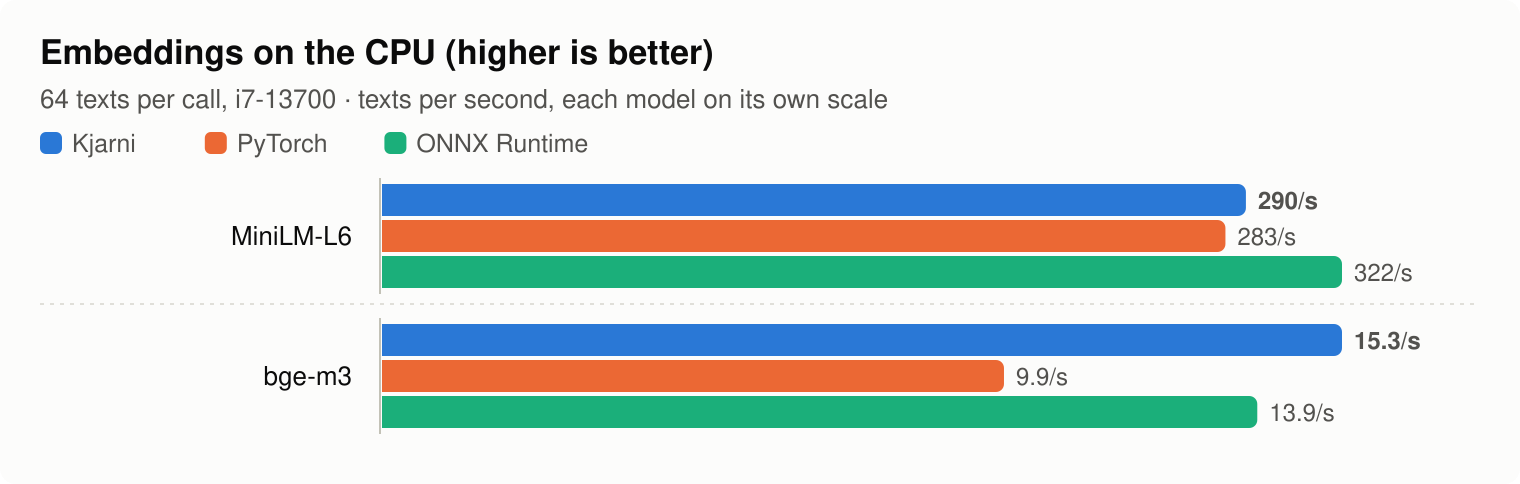
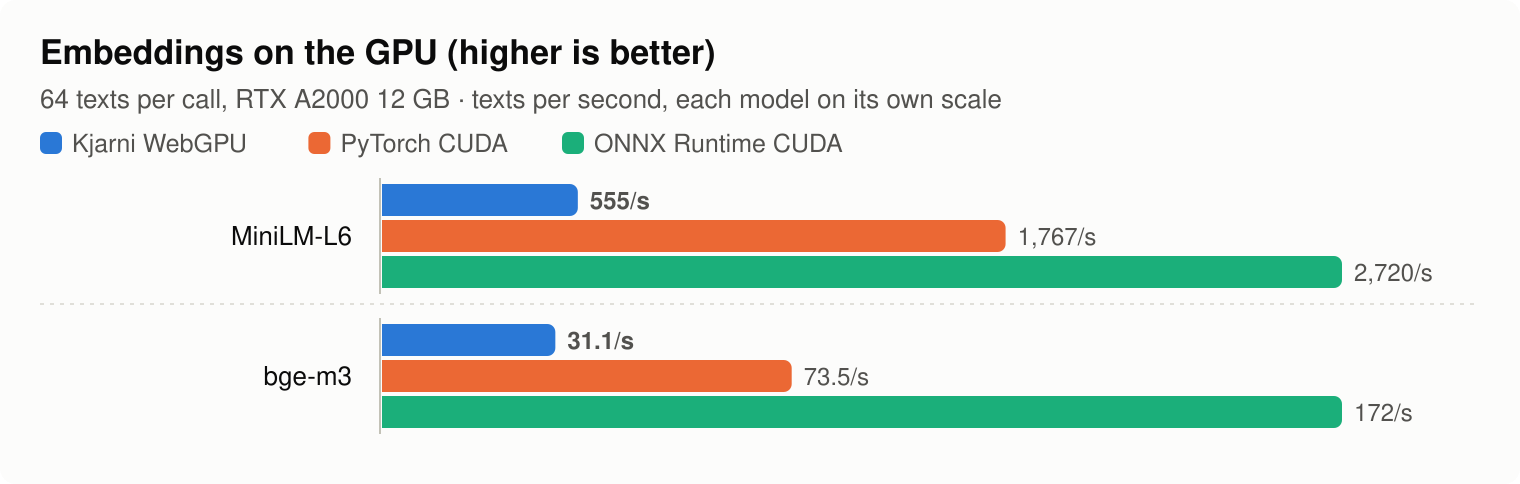
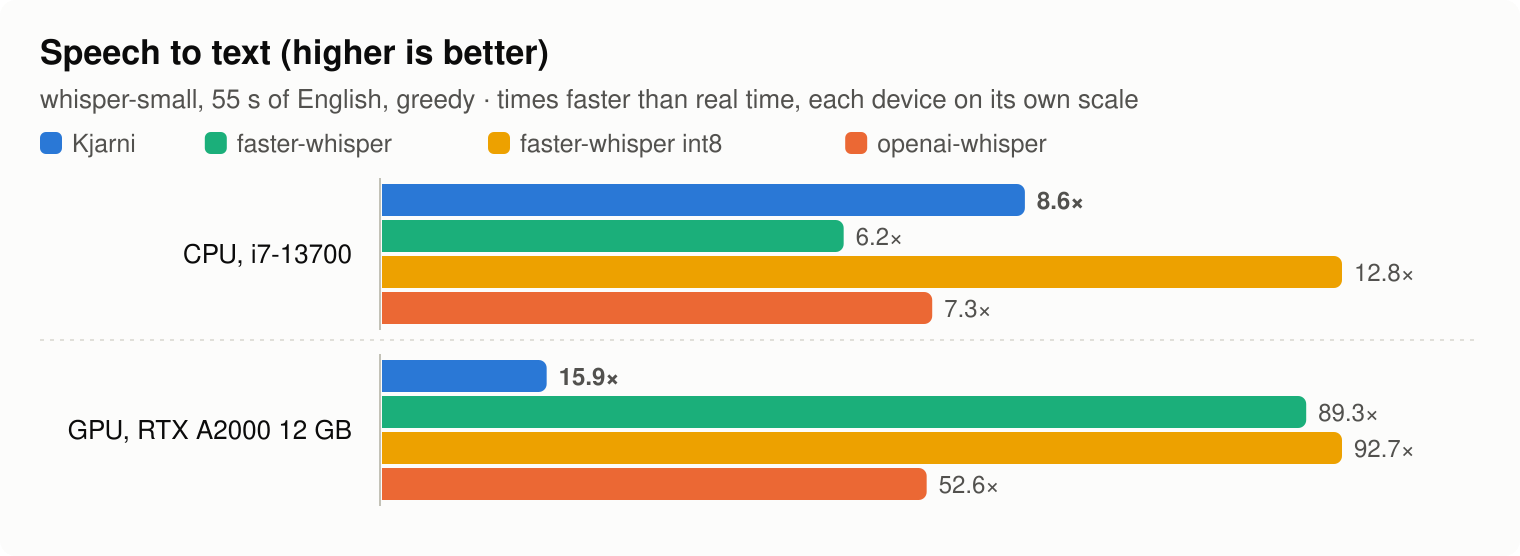
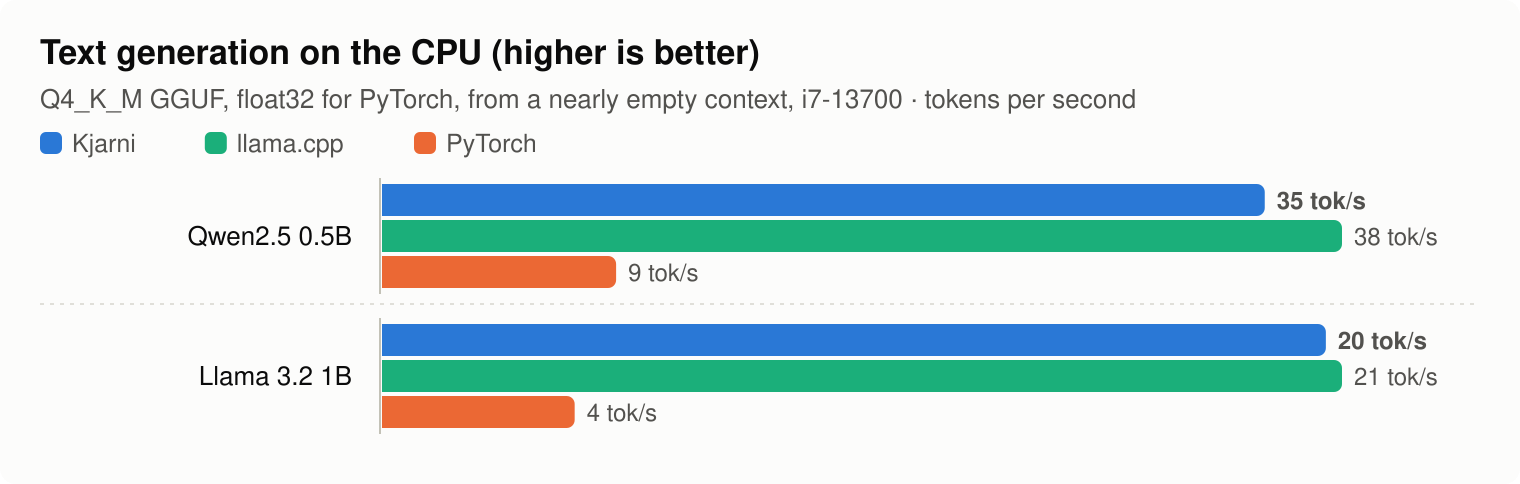
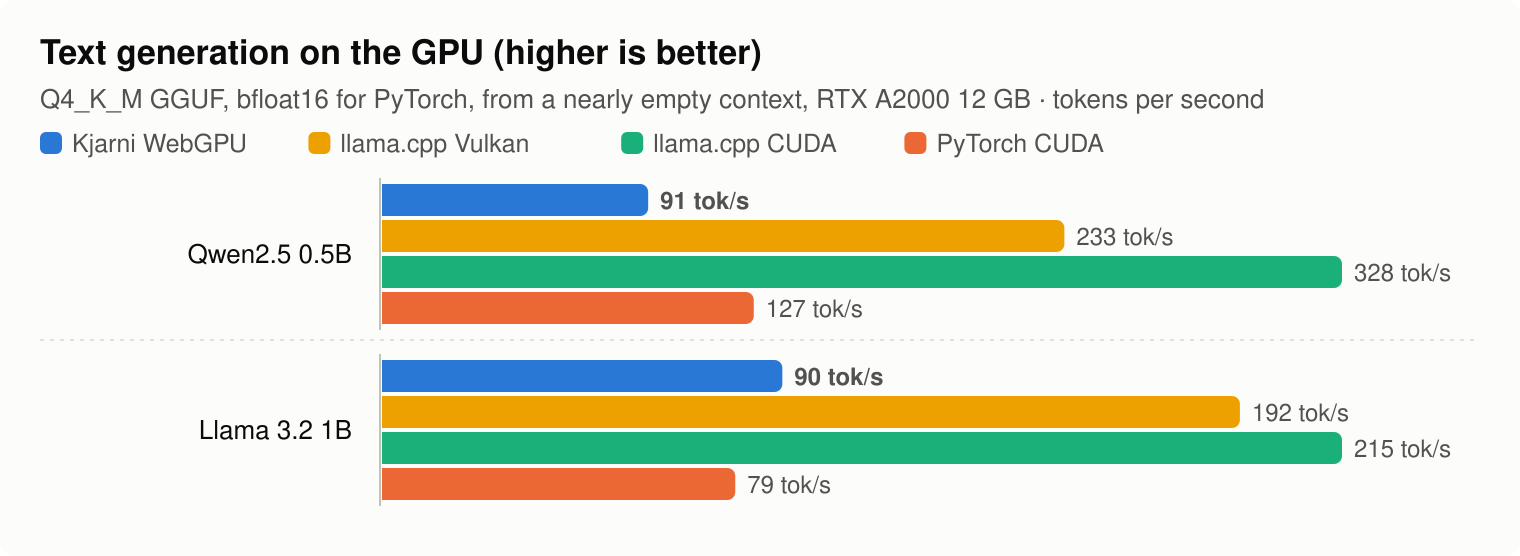
These are the Rust engine's own numbers measured through its bindings; the Rust API and the C ABI take the same time, 3.43 and 3.44 ms for one short MiniLM embedding. Method and every number: BENCHMARKS.md.
The same engine elsewhere
One engine, one set of kernels, the same numbers from every language.
- kjarni.ai - documentation and worked examples
- GitHub - source, issues, releases
- NuGet - from C#
- PyPI - from Python
- npm - in the browser, via WebAssembly
- Go module - from Go
- Why I Built a Native ML Inference Engine in Rust - the reasoning
- Semantic Search in C++ - the C ABI used directly
- ML from the Command Line - the same models as a UNIX tool
License
MIT or Apache-2.0.