
jevr is a simple, lightweight, blazing-fast information-retrieval CLI built
from exactly two ingredients: a local, stateless BM25 pass for recall,
and TypeSafe Jev calibrated judgments for
precision. No embeddings, no vector database, no index directory, no
repository state — point it at any codebase or plain-text document corpus
(markdown, rst, txt, html, org, tex, ...) and ask a question.
Ask "where is the websocket reconnect logic?" or "how do I configure retry backoff?" and get back a ranked list of files and line ranges, each with a calibrated relevance probability — ready to open at the right spot. That recipe scores 0.900 any-gold@10 on SWE-bench Lite file localization and beats published BM25 and cross-encoder baselines on BEIR, at roughly 2 seconds and a cent per cold query (benchmarks).
Demo
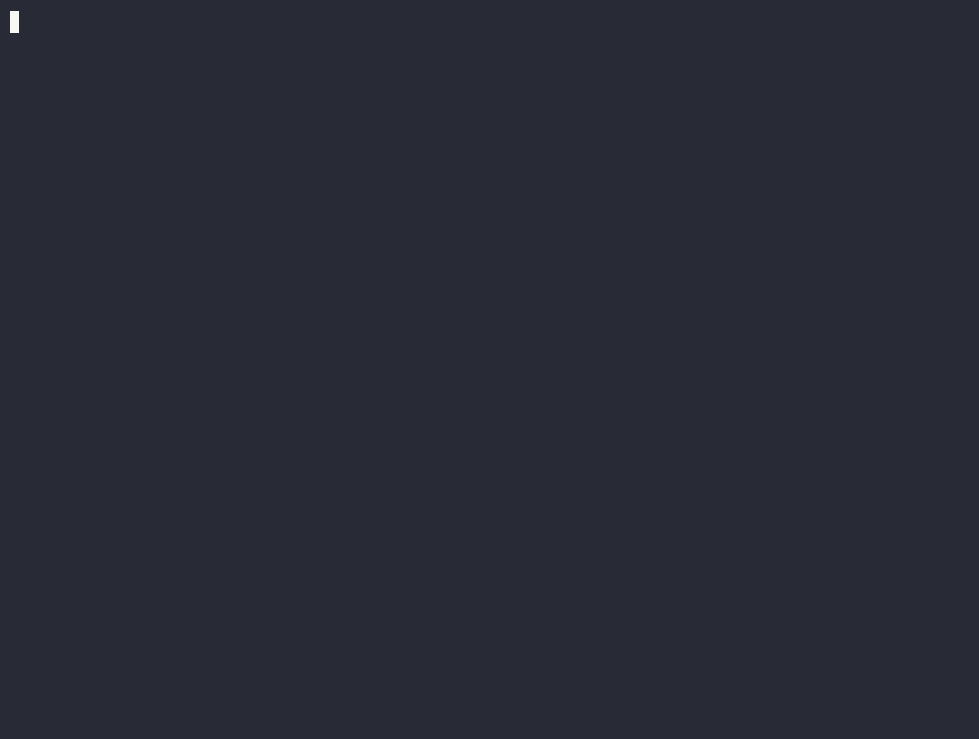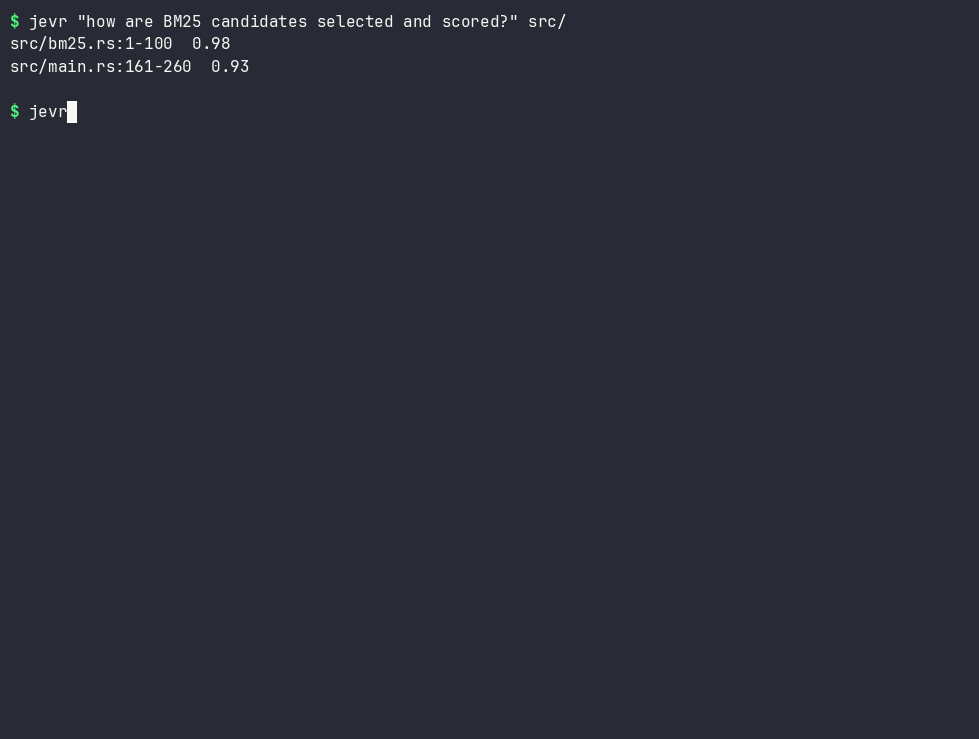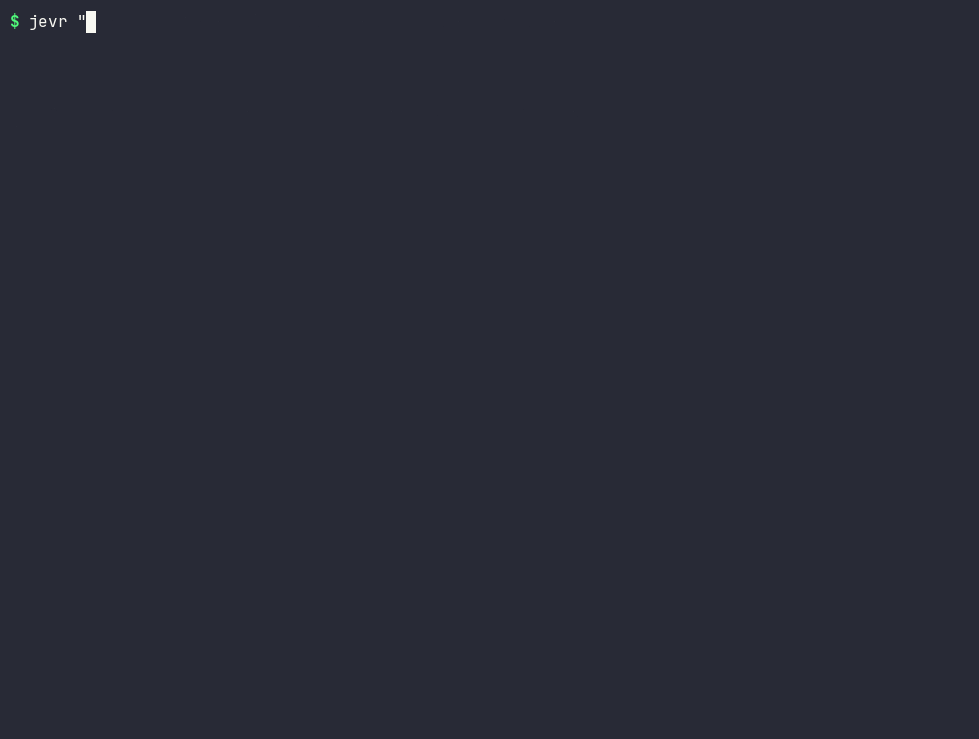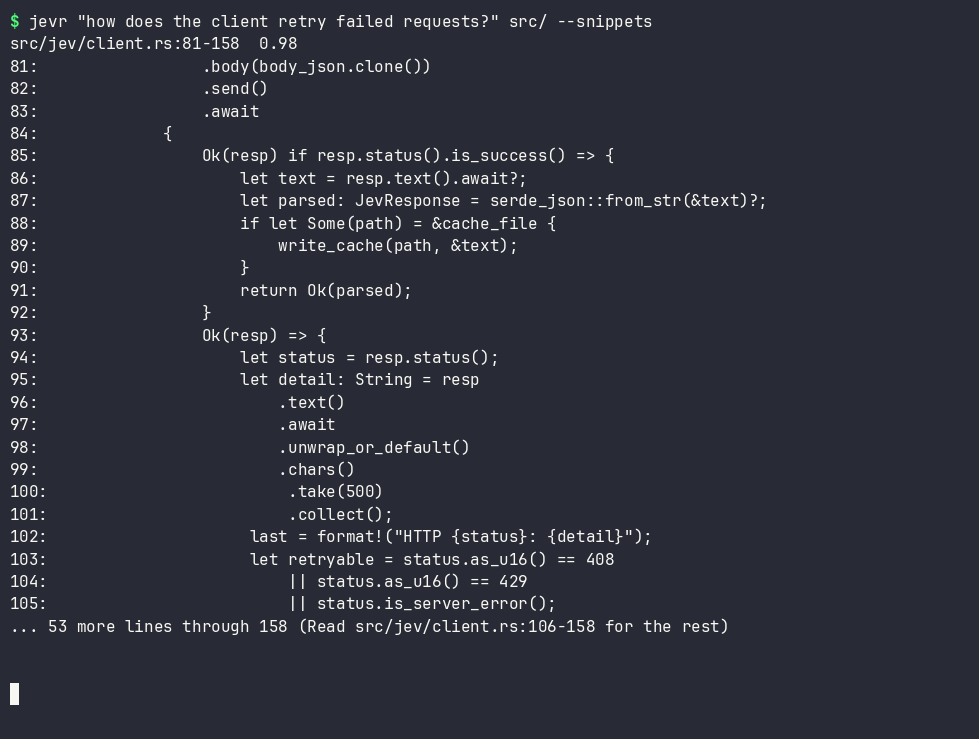
Each result line is path:start-end score — the line range of the
best-matching window and its calibrated 0..1 relevance score. The interface
is deliberately grep-shaped (positional query + optional positional path,
grep exit codes, path:line locations) so coding agents can use it from
muscle memory, without steering or instructions.
Highlights
- Query in plain language. "how does crash recovery work?" beats
guessing identifier names into
rg -i "recover|restart|resume". - Calibrated scores, not keyword hits. Every result carries a relevance probability from a model built for exactly this kind of typed judgment; a 0.97 means something, and so does a 0.31.
- Grep-honest exit codes.
0matches,1none above threshold,2error — and a closed pipe (| head) ends output cleanly. - Code and documents in one tool, verified by separate calibrated question sets so neither lane perturbs the other.
- No repository state. The BM25 index is rebuilt per invocation
(~1 s at repo scale); responses are cached under
~/.cache/jevr/, so repeated queries over unchanged code are instant and free. - Measured, not vibed. Defaults are benchmark-derived operating points — docs/BENCHMARKS.md records the evidence and the ablations that were tested and rejected.
Benchmarks
| Benchmark | Metric | jevr | Anchors |
|---|---|---|---|
| SWE-bench Lite, file localization (50-sample) | any-gold@10 | 0.900 | BM25@27K 0.513 · Agentless (GPT-4o) 0.697 |
| Loc-Bench V1, Feature Request (30-sample) | any-gold@10 | 0.700 | multi-turn agent loops 0.675–0.834 (strict, full set) |
| BEIR SciFact (300 queries) | nDCG@10 | 0.778 | BM25 0.665 · BM25+CE 0.688 · best zero-shot reranker 0.777 |
| BEIR NFCorpus (323 queries) | nDCG@10 | 0.363 | BM25 0.325 · BM25+CE 0.350 · best zero-shot reranker 0.399 |
On SciFact the pipeline edges past the best published zero-shot reranker number we could verify — at ~2 s per query where those systems report 30–76 s. On NFCorpus it beats the BM25 and cross-encoder baselines but does not reach the LLM-reranker frontier. A single benchmark is never enough: protocols, caveats, and rejected ablations are in docs/BENCHMARKS.md, and the BEIR numbers are reproducible with the scripts in benchmarks/.
Installation
Requires Rust 1.88+ and a TypeSafe API key.
# required at runtime
Or from a clone:
Claude Code plugin
The repo ships a Claude Code skill that teaches agents to reach for jevr
instead of grep+glob when a search is conceptual. One command from a clone:
or, inside Claude Code: /plugin marketplace add romeromarcelo/jev-retrieval
then /plugin install jevr@jevr. The skill source lives in
skills/using-jevr/.
Usage
# Bare natural-language query — the recommended calling pattern
# Scope to a subtree or a single file, grep-style
# Documents work the same way — point PATH at any text corpus
# Show each file's best-matching lines, rg-style
# Full verdicts as JSON (--top-k applies in every mode)
# Bring your own candidates (bypasses Stage 1 entirely)
Prefer bare queries: supplying hand-tuned -k keyword variants measured
worse than the plain question (macro-F1 0.614 vs 0.673 — see the
technical guide).
Output
Results are ordered by relevance (a listwise rerank when it succeeds, score
order otherwise). Code results print first, then document results — each lane
keeps its own threshold, rerank, and top-k cap — and whenever documents
print, one stderr line announces the split (e.g. jevr: 7 code result(s) kept at score >= 0.90, then 3 document result(s) kept at score >= 0.60).
--snippets adds the best window's body with N:-prefixed line numbers,
capped at snippet_lines (default 25) per file; a cut snippet ends with a
... N more lines (Read path:A-B for the rest) pointer. --json carries the
full snippet. Paths print prefixed with the PATH argument exactly as you gave
it, so they open directly from your working directory.
When nothing clears the threshold (e.g. a bug report rather than a concept), the best few verdicts are still printed — flagged with a stderr notice and exit code 1 — so a calling agent can judge by score instead of getting silence.
Flags
| Flag | Effect |
|---|---|
[PATH] (positional) |
Directory or file to search (default .) |
-p, --path <PATH> |
Same as the positional PATH |
-k, --keywords <CSV> |
Comma-keyword Stage-1 variant (repeatable, ≤4) |
--candidates <FILE> |
Repo-relative paths, one per line; skips Stage 1 |
--threshold <F> |
Minimum relevance score to keep a file (defaults: 0.90 code, 0.60 docs; sets both) |
--top-k <N> |
Maximum files printed per lane — code and documents separately (default 10) |
--model <ID> |
Jev model (default pinned jev-1.13.0) |
--config <FILE> |
Explicit YAML config file |
--concurrency <N> |
Concurrent verification requests (default 32) |
--no-grep-union |
Disable the git-grep literal-vocabulary union |
--no-cache |
Disable the response cache; every request is billed |
--hidden |
Include hidden files and directories |
--paths-only / --snippets / --json |
Output mode (mutually exclusive; default --paths-only) |
-V, --version |
Print version |
How it works
- Stage 1 — candidates (local, ~1 s, free). A gitignore-aware walk
feeds an in-memory BM25 index with a code-aware tokenizer; the top files
per lane are unioned with
git grephits. Nothing is persisted. - Stage 2 — verification (Jev, concurrent, ~2 s). Every candidate is split into overlapping 100-line windows; each window and the whole file get a calibrated relevance probability from measured question phrasings.
- Stage 3 — ranking (Jev, one request per lane). A single listwise question orders each lane's kept files.
The full machinery — window caps, question phrasing evidence, retry and cache policy, per-tunable rationale — is documented in the technical guide.
When not to use jevr
- You know the exact string. For literal strings, regexes, or known
symbol names,
grep/rgis faster and free. The tools compose: one jevr query reveals the real symbol names, one grep then finds every occurrence. - You have no API key or budget. Stage 2/3 call a paid network API
(roughly a cent per cold query; warm repeats are free via the response
cache under
~/.cache/jevr/). - You need offline or air-gapped search. Verification requires network access.
Configuration
Precedence: defaults < YAML file (--config, else .jevr.yaml in the repo
root, else ~/.config/jevr.yaml) < CLI flags. Every default is a measured
operating point; the full YAML reference with per-key rationale is in the
technical guide.
Building and testing
Score-affecting changes (thresholds, question phrasing, windowing, request caps) need benchmark evidence — see the development invariants and docs/BENCHMARKS.md.
License
Licensed under the Apache License, Version 2.0 (LICENSE.md or http://www.apache.org/licenses/LICENSE-2.0).
Unless you explicitly state otherwise, any contribution intentionally submitted for inclusion in the work by you, as defined in the Apache-2.0 license, shall be licensed as above, without any additional terms or conditions.