
incin
A Rust deep learning framework with compile-time verification of tensor shapes, dtypes, devices, and gradient state.




Quick start · Why incin · The tooling · The Book
Incin puts tensor shapes, dtypes, devices, and gradient state into Rust's type
system. A matmul between incompatible matrices is a compile error. Training a
frozen parameter is a compile error. Feeding f32 where the kernel demands
u32 indices? Compile error.
You find all of this out in cargo check, seconds after typing, instead of in
a runtime failure days into a training run.
The demo
use *;
let x: , DefaultBackend> = zeros?;
let w: , DefaultBackend> = zeros?;
let y = x.matmul?; // [4, 8] x [8, 2] -> [4, 2]. Compiles.
let bad: , DefaultBackend> = zeros?;
let _ = x.matmul?; // inner dims: 8 vs 3. Does NOT compile.
Plain cargo check shows you the raw typenum soup:
error[E0277]: Cannot contract dimension `UInt<UInt<UInt<UInt<UTerm, B1>, B0>, B0>, B0>`
              with `UInt<UInt<UTerm, B1>, B1>`
cargo incin check intercepts that and prints what you
actually wanted:
error[E0277]: Cannot contract dimension `[4, 8]` with `MatMulShape<[3, 8]>`
  --> src/main.rs:9:22

  └── 💡 [Typenum Translation Hints]:
      • 4  <= UInt<UInt<UInt<UTerm, B1>, B0>, B0>
      • 8  <= UInt<UInt<UInt<UInt<UTerm, B1>, B0>, B0>, B0>
      • 3  <= UInt<UInt<UTerm, B1>, B1>
Same error, readable shapes, zero runtime cost. The types prove the shapes; the numbers are covered too: every operation comes from one canonical catalog backed by generated conformance vectors, and the differentiable ones carry finite-difference gradcheck suites. And with incin-lsp, rust-analyzer shows shapes as decimal hints directly in your editor while you type.
Why another deep learning framework?
Because "shape mismatch at runtime" was never a necessary trade-off. Python frameworks check shapes when the kernel launches; by then you've already paid for the queue, the data load, and three minutes of your life. Incin moves that check to the type system, which means:
- If it compiles, the shapes agree. Not "probably agree": the compiler proved it.
- Dynamic shapes are still first-class. Real models have runtime batch
sizes and sequence lengths.
Tensor<Dyn, B>composes with static shapes in the same program, and every dynamic transition is checked before a kernel sees bad metadata. - Every operation is declared once, in a canonical catalog with generated semantics docs and conformance vectors. No drift between what the docs claim and what a backend does.
- No silent fallbacks. If a backend can't run an operation, you get a type error naming the gap, never a quiet transfer to another device.
Under the hood there's an autograd tape, AdamW/SGD, conv/pool/norm/loss layers, safetensors checkpoints, ONNX import for supported graphs, and CPU executors for all 158 backend-executable catalog operations, checked against generated conformance vectors, with finite-difference gradchecks over the differentiable kernels. The full honest status, including what's not done, lives in what's not finished.
Quick start
0.1.0 hasn't shipped to crates.io yet, so point at master:
[]
= { = "https://github.com/xupremix/incin", = "master" }
Define a model, train it, keep every shape known at compile time:
use *;
s![dyn, 784] is the batch axis left dynamic; everything else is proven at
compile time. The output spells out f32 and Grad because a forward pass
through parameters joins their gradient state into the result type. Swap in
AdamW, add a loss from
incin::nn, iterate a
DataLoader,
and you have a training loop.
Prefer to explore first? The default build needs nothing but a Rust toolchain:
use *;
More in the Book's quickstart,
including slicing with i![], ONNX import via import_model!, and Hugging Face
downloads through the data-hub feature.
The tooling is the feature
Type-level shape systems have a dirty secret: raw compiler diagnostics are unreadable. Incin ships the fix as part of the framework, not as a plugin you have to go find.
cargo incin wraps cargo itself. check, build, test, run, clippy
all pass through with typenum noise translated to decimal shapes as it streams.
It also inspects model files and translates pasted errors:
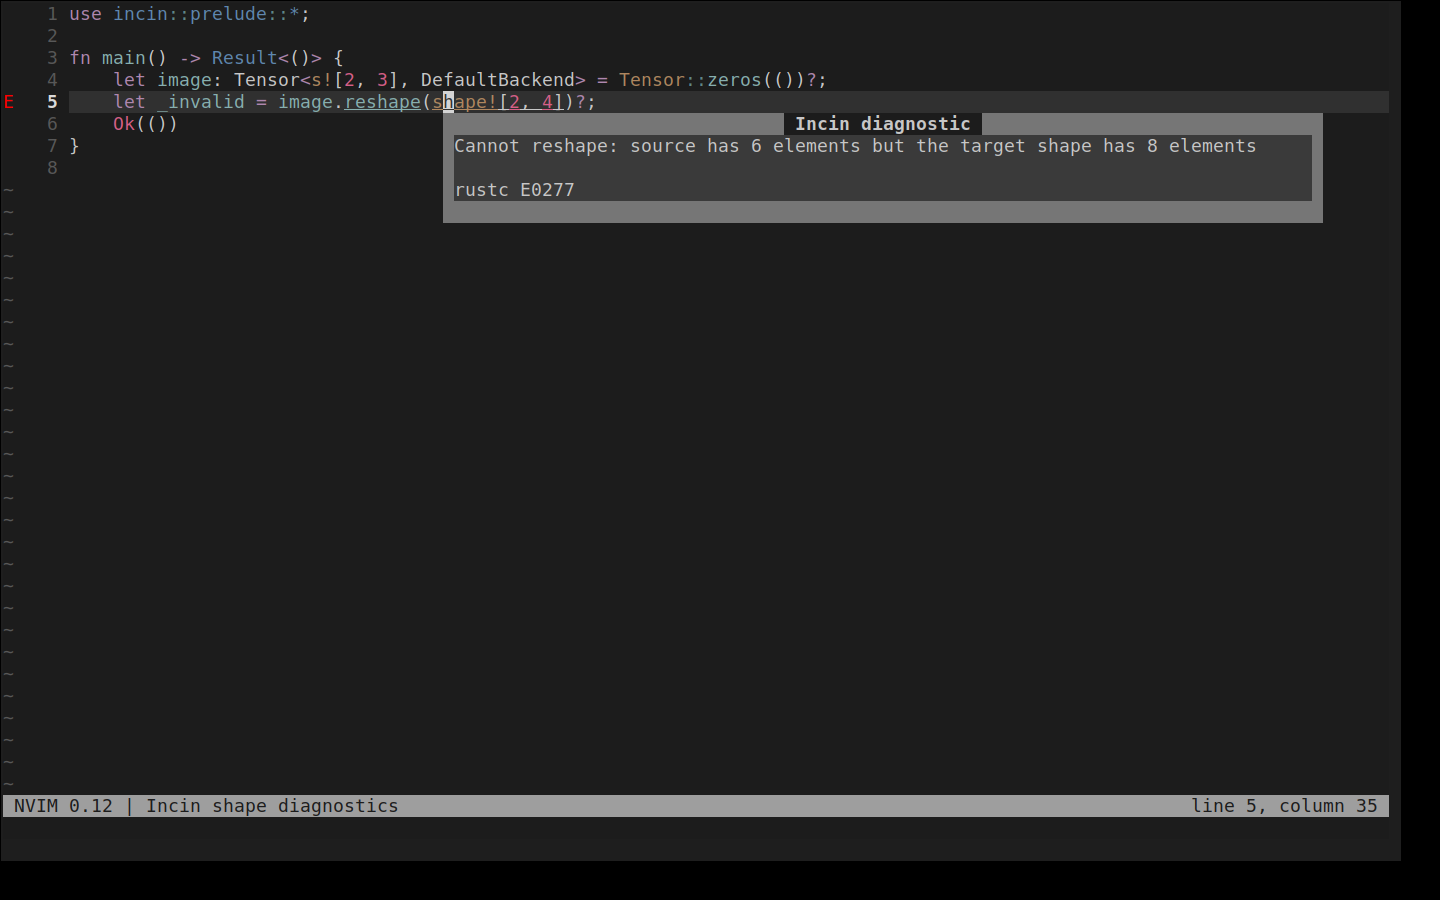
incin-lsp proxies rust-analyzer and rewrites diagnostics, hover types,
and inlay hints with the same engine. Tensor types render as [4, 8], not
UInt<UInt<...>>. Verified in VS Code and Neovim:
incin-viz is a terminal UI for watching training runs live (losses,
gradient norms, memory, graph snapshots) over a local telemetry socket.
Three tools, one diagnostic engine, no configuration required.
# Default: std + native CPU backend
= { = "https://github.com/xupremix/incin", = "master" }
# Add WGPU
= { = "https://github.com/xupremix/incin", = ["wgpu"], = "master" }
# CUDA-only application
= { = "https://github.com/xupremix/incin", = false,
features = ["std", "cuda"], branch = "master" }
# Candle interop
= { = "https://github.com/xupremix/incin", = ["external-candle"], = "master" }
These become "0.1.0"-style version deps once crates.io publication lands.
incin-backends: defaults tostd,cpu; optionalcompiled,cpu-blas,cuda,cuda-vendor,wgpu,metal,metal-mps,autotune,external-candle,telemetry,distributed,distributed-reference,distributed-nccl, andtest-utils.incin-core: defaults tostd; optionalnightly,paranoid-validation,distributed,cuda,wgpu,metal,compiled,postcard,safetensors, andserde_json.incin-macros: defaults tostd; optionalnightlyanddistributed.incin-diagnostics: defaults tostd.incin-data: defaults todownload; optionalhub.incin-telemetry,incin-viz,incin-viz-plugin-api, andincin-lspexpose no Cargo features.
What's inside
incin/
├── incin               Facade: prelude, macros, cargo-incin CLI
├── incin-core          Typed tensors, op catalog, autograd contracts, graphs
├── incin-backends      CPU (complete) · CUDA/WGPU/Metal (preview) · Candle adapter
├── incin-data          Data loading, datasets, Hugging Face Hub
├── incin-telemetry     Event emission and transport streams
├── incin-viz           Terminal training visualizer (+ plugin API)
├── incin-diagnostics   Typenum → decimal shape translation engine
└── incin-lsp           Editor proxy: rust-analyzer in, readable shapes out
A Tensor<S, B, K, G> carries its Shape, Backend, dtype Kind, and Gradient
state as type parameters. Methods build validated operation descriptors and
dispatch to the backend's executor. Missing executor? Type error. Wrong device?
Type error. Nothing switches backends behind your back.
| Feature | Tier | Prerequisites | Default | Enables | Incompatibilities | Purpose |
|---|---|---|---|---|---|---|
std |
stable | none | yes | incin-core/std, incin-macros/std, incin-backends/std |
none | Enables standard-library functionality, serialization, and filesystem APIs. |
nightly |
preview | none | no | incin-core/nightly, incin-macros/nightly |
none | Enables nightly-only APIs in the core and macro crates. |
cpu |
stable | std |
yes | std, incin-backends/cpu |
none | Enables the built-in CPU backend. This is the only default backend. |
cpu-blas |
stable | std, cpu |
no | std, cpu, incin-backends/cpu-blas |
none | Hands large f32 CPU matmuls to a blocked GEMM. The CPU backend is complete without it; see incin-backends for what it does and does not change. |
cuda |
preview | std |
no | std, incin-core/cuda, incin-backends/cuda |
none | Preview: the native CUDA backend, covering the subset in docs/capabilities.md. Never enabled implicitly. |
wgpu |
preview | std |
no | std, incin-backends/wgpu |
none | Preview: the cross-platform WGPU backend, covering the subset in docs/capabilities.md. Never enabled implicitly. |
metal |
preview | std |
no | std, incin-backends/metal |
none | Preview: the native Metal backend for Apple Silicon. Its executors are stubs pending MTL-002/003; see docs/capabilities.md. Never enabled implicitly. |
metal-mps |
preview | metal |
no | metal, incin-backends/metal-mps |
none | Enables MPS and MPSGraph structured primitives for Apple Silicon. |
external-candle |
stable | std |
no | std, incin-backends/external-candle |
none | Enables the external Candle backend at incin::external::candle. |
autotune |
preview | cuda |
no | cuda, incin-backends/autotune |
none | Enables CUDA launch autotuning. |
train |
preview | std |
no | std |
none | Enables the preview trainer at incin::experimental::training. The interface may change without a migration path. |
distributed |
preview | none | no | incin-core/distributed, incin-macros/distributed |
none | Preview: typed meshes, static/runtime tensor placements, and distributed lowering proofs. This is a planning and validation layer; there is no distributed execution path. Transports remain separate opt-in backend features. |
distributed-reference |
preview | distributed |
no | distributed, incin-backends/distributed-reference |
none | Enables the deterministic in-process collective transport used by conformance tests and local distributed-plan development. |
distributed-nccl |
preview | distributed, cuda |
no | distributed, cuda, incin-backends/distributed-nccl |
none | Two-host process-per-rank CUDA transport and its TCP bootstrap. |
telemetry |
stable | std |
no | std, incin-backends/telemetry, dep:incin-telemetry |
none | Enables backend telemetry hooks. cargo incin doctor also reports the run directory under this feature, which is why the dependency is direct here and not only through incin-backends. |
test-utils |
test-only | std, cpu |
no | std, cpu, incin-backends/test-utils |
none | Deterministic fault-injection hooks for tests. No stand-in backend: a test that needs a backend uses a real one. |
backend-authoring |
stable | none | no | none | none | Extension contracts for backend authors. |
data-hub |
stable | std |
no | std, incin-data/hub |
none | The Hugging Face Hub client at incin::hub. Off by default because it brings an async runtime and a second TLS stack into the dependency graph for an API most training code never calls; dataset downloading does not need it. |
compiled |
preview | std, cpu |
no | std, cpu, incin-core/compiled, incin-backends/compiled |
none | Preview-only CPU reference evaluator and plan-inspection types under incin::experimental::compiled. No stable API, deployment format, or portable artifact ABI is promised. |
hardware-tests |
hardware-only | distributed-nccl |
no | distributed-nccl |
none | Opt-in only: ignored multi-host CUDA runtime fixtures require actual hardware and are not part of compile-only feature coverage. |
| Variable | Purpose |
|---|---|
INCIN_HUB_CACHE_DIR |
Custom cache directory for Hub downloads (defaults to ~/.cache/huggingface/hub). |
INCIN_HUB_TOKEN |
Authorization token for private Hugging Face Hub repositories. |
INCIN_NO_META |
Set to 1 to bypass the .incin_meta cache and force full ONNX re-parsing during macro compilation. |
Install the proxy, point your editor at it, done:
| Editor | Status | Guide |
|---|---|---|
| VS Code | Verified end to end | editors/vscode/README.md |
| Neovim 0.11+ | Verified end to end | editors/nvim/README.md |
| RustRover | External-tool fallback verified | editors/rustrover/README.md |
Neovim screenshot for good measure:
Where to go next
- The Book is the task-oriented guide, from five-line tensors up to a Transformer block.
- What's not finished is the honest list. GPU backends cover a subset; read it before planning a CUDA training run.
- Capability matrix is per-operation, generated from executor registrations, never hand-edited.
- docs/GUIDE.md is the repository-side tour of the shape-proof system.
- The deep dive runs five rendered chapters on the execution model: how a typed call becomes a kernel, what each stage proves, and how to add your own backends, devices, and dtypes.
- Found something? Open an issue. The templates make it fast.
Because a shape mismatch belongs in cargo check, not on epoch 40, at 3 AM, on a Saturday.
License
Dual-licensed under either MIT or Apache 2.0 at your option.