
fanring
Fast typed MPSC and MPMC channels built from one SPSC yring per producer.
Sender registration is dynamic. Each sender writes to its own ring, so producers do not contend on a shared queue tail. MPSC drains those rings directly; MPMC stages prefetched batches in stealable receiver-local queues.
Deferred teardown is the default and avoids cleanup coordination on sends.
Choose Coordinated to reclaim unread payloads independently of idle sender
lifetimes.
Requires Rust 1.93 or newer.
| Nonblocking | Blocking | Timeout | Deadline | |
|---|---|---|---|---|
| Send | try_send |
send |
send_timeout |
send_deadline |
| Receive | try_recv |
recv |
recv_timeout |
recv_deadline |
Performance
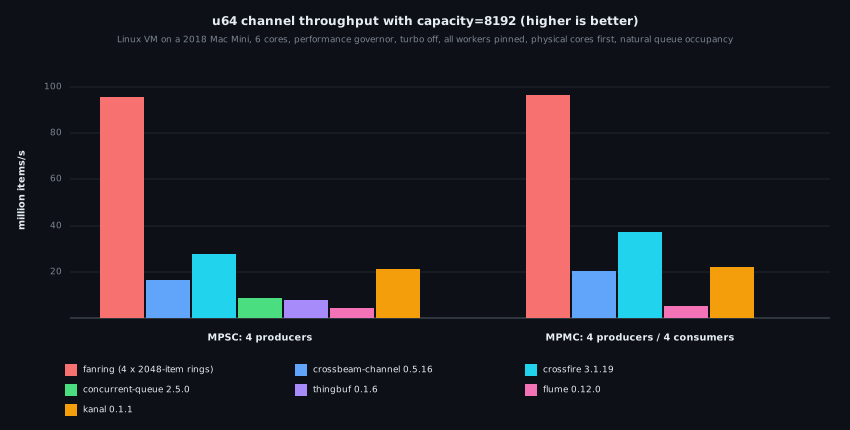
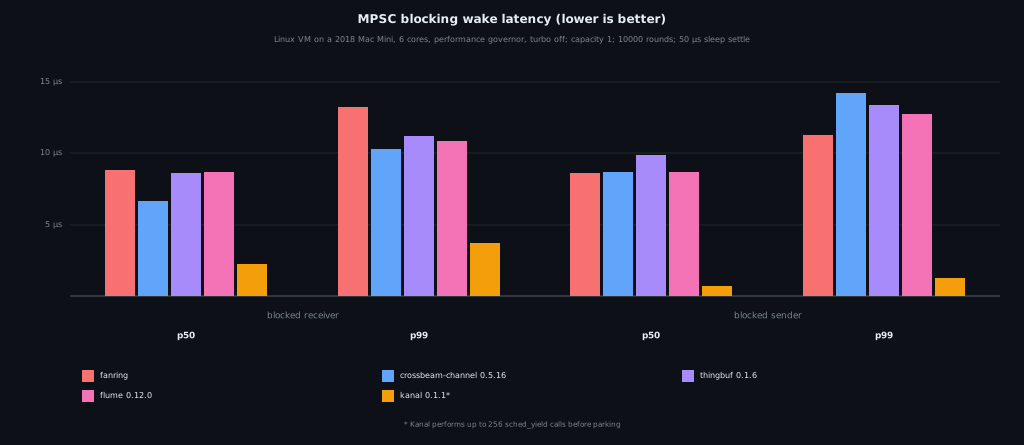
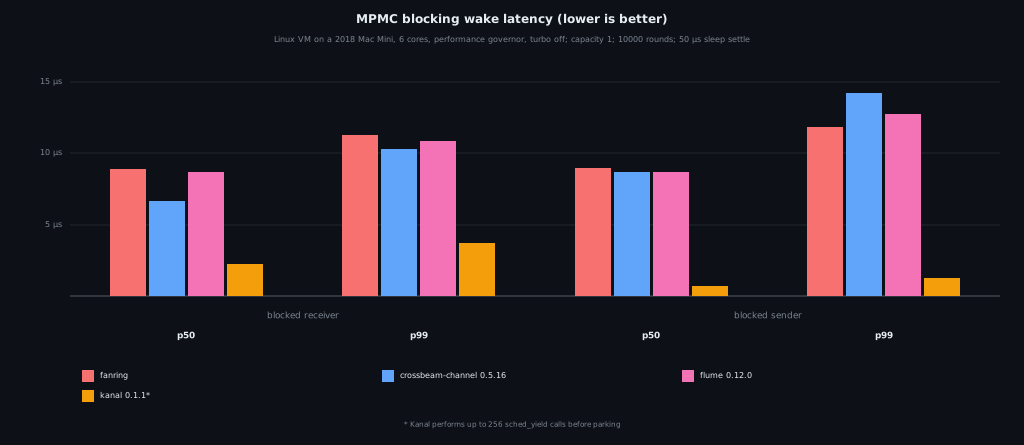
Median throughput and blocking wake latency on the system named in each
chart, measured with the performance governor and CPU turbo disabled.
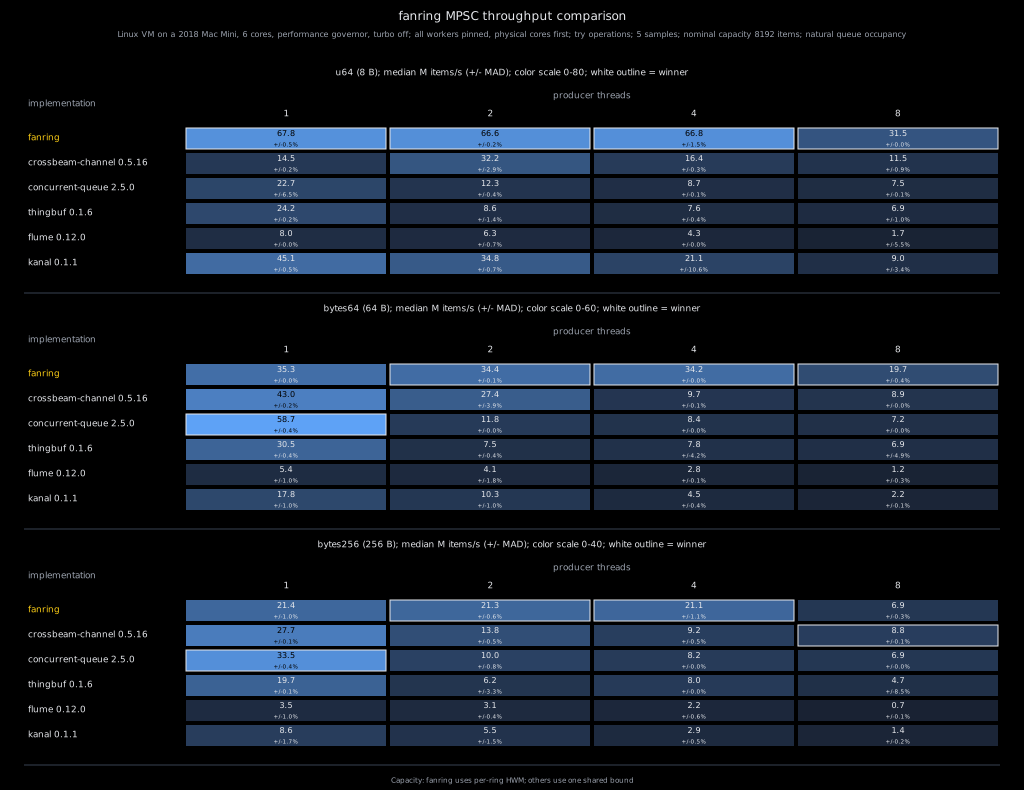
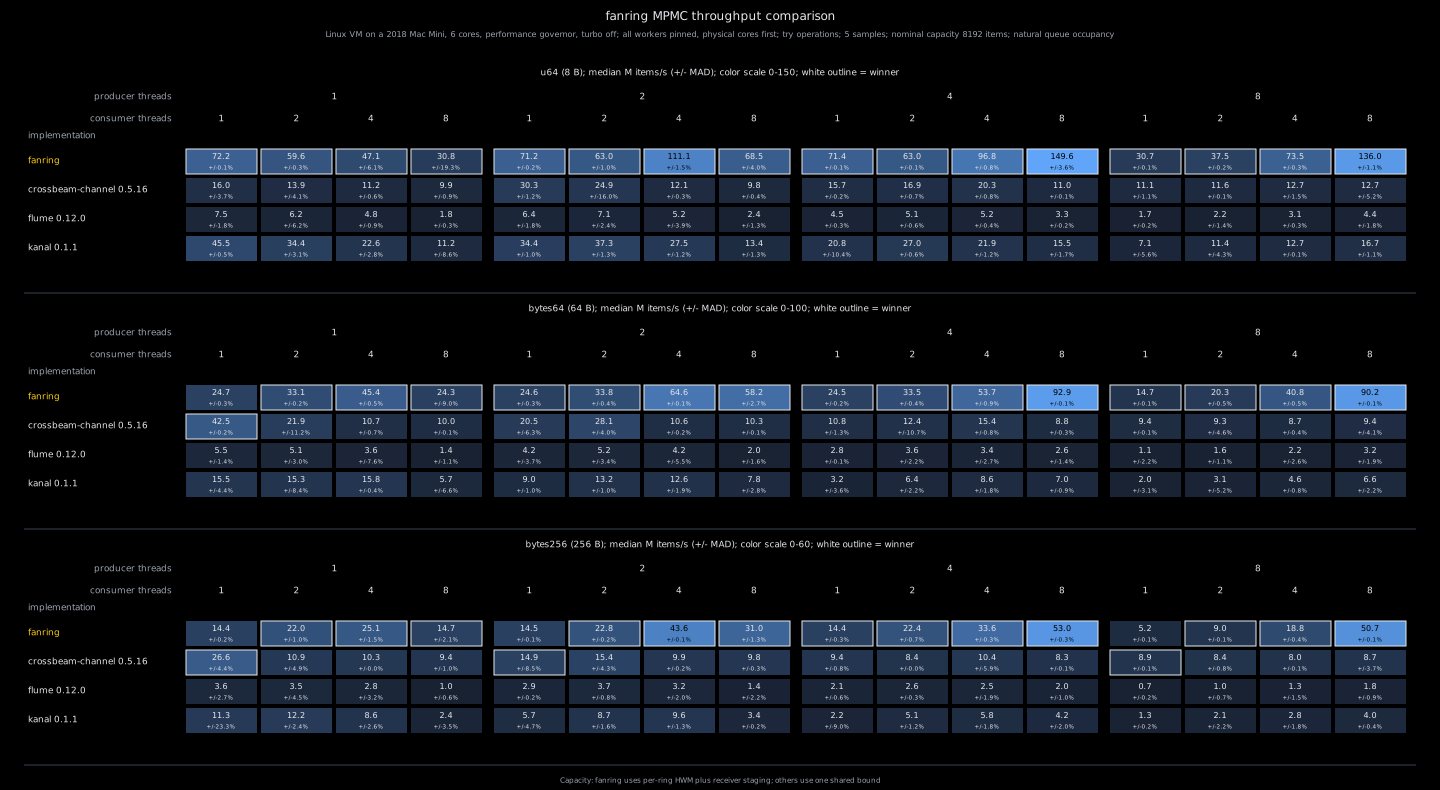
Detailed throughput heatmaps cover thread counts and payload sizes.
Detailed MPSC
Detailed MPMC
MPSC wake latency
MPMC wake latency
Teardown policies
Deferred is the default teardown policy: unread ring payloads may remain
alive until their sender drops. Choose Coordinated when queued replies,
permits, or buffers must be released independently of idle sender lifetimes:
use ;
let = ;
The policy is part of the endpoint types and inherited by cloned handles.
Coordinated teardown drains unread values; overlapping sends clean up late
publications when they resume. Receiver drop does not wait for paused producers.
The additional send coordination has a measurable cost:
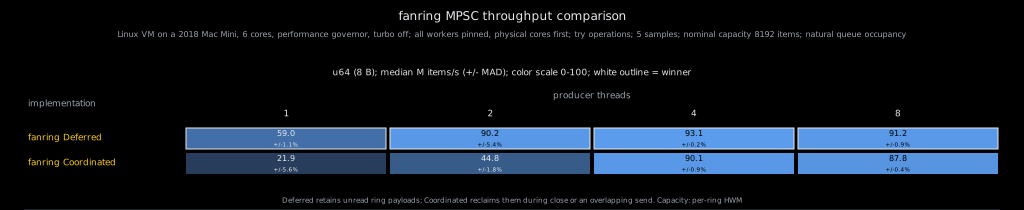
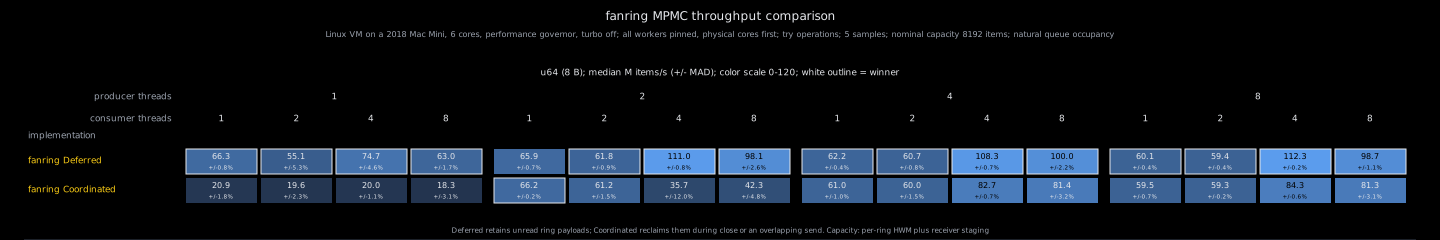
The general comparison and wake-latency charts above use Deferred for fanring.
These policy charts compare u64 traffic under both policies on the same system.
See teardown contracts, reproduction, and observed behavior in other channels.
The pinned bounded Crossbeam, Crossfire, Flume, Kanal, and Thingbuf versions all
retain unread payloads in our receiver-drop probe while senders remain alive.
This is a payload-lifetime distinction; successful send still does not guarantee
that application code processes the message.
MPSC
use channel;
let = channel;
let mut tx1 = tx0.try_clone.expect;
tx0.send.unwrap;
tx1.send.unwrap;
for _ in 0..2
assert_eq!;
drop;
assert_eq!;
mpsc preserves FIFO within each sender lane and relaxes order across senders.
Single-value receives batch slot release: receiving a value may leave its slot
unavailable to the sender until a later receive. Call rx.release_consumed()
before returning application permits or issuing completions that allow more
sends. This publishes freed slots across sender lanes and wakes blocked senders.
To receive a bounded batch into reusable storage:
let mut batch = Vecwith_capacity;
while rx.recv_batch_into.is_ok
recv_batch_into appends at most the requested limit, waits only for the first
value, and releases consumed slots before returning. It returns the number
appended; a partial batch succeeds even after disconnect. Reserve enough spare
vector capacity to avoid output reallocations. A zero limit receives nothing,
releases consumed slots, and returns Ok(0).
MPMC
use channel;
let = channel;
let mut rx1 = rx0.clone;
tx.send.unwrap;
tx.send.unwrap;
let a = rx0.recv.unwrap;
let b = rx1.recv.unwrap;
assert_ne!;
mpmc drains up to 64 values from a ready sender ring. With one receiver, the
remaining values stay in a private deque. Cloning publishes that deque before
the new receiver becomes visible. With multiple receivers, remaining values
enter bounded synchronized work queues, and competitors steal up to eight at a
time. Receiver drop republishes its buffered work. Ordering is relaxed. Moving
values into that second-stage queue costs more for large inline types; box large
payloads when move bandwidth dominates.
mpmc::try_recv may return a transient Empty while bounded lane maintenance
or another receiver moves work. Disconnected is final: all senders are gone,
sender rings and staged queues are drained, and no work publication is in
flight.
Contract
- One bounded ring per dynamic sender; capacity is a per-sender HWM rounded up to a power of two.
- MPSC preserves FIFO within each sender lane. MPMC ordering is relaxed and its receiver staging can temporarily exceed sender-ring capacity.
- Nonblocking, blocking, timeout, and deadline operations are available. Blocking operations spin briefly before parking.
- Dropping the last sender preserves buffered values for receivers to drain.
Last-receiver drop follows the chosen teardown policy. MPMC
Emptymay be transient while receivers move internal work;Disconnectedis final. - Sender hot paths and MPSC batching avoid a shared queue lock. MPMC work distribution and topology maintenance use mutexes; blocking operations may park.
Good Fit
- Many long-lived or frequently changing producers feeding one or more consumers.
- MPSC callers need only per-producer FIFO; MPMC callers accept relaxed order.
- Per-producer HWM matches the desired backpressure model.
- Callers can use built-in parking or own the backoff policy around
try_*.
Bad Fit
- Need global FIFO or strict one-item round robin.
- Need one exact capacity shared across all producers.
- Need an exact total MPMC bound that includes receiver staging.
- Need async wakeups.
Further reading
- More detail: DESIGN.md
- Development and benchmark reproduction: DEVELOPMENT.md
- Release history: CHANGELOG.md